# AWS opens an agent evaluation framework
> Test design matters when comparing agent behavior.
By BIGCHANGE.AI Editorial
Published: 2026-11-11T21:17:38.499Z
Updated: 2026-11-11T21:17:38.499Z
Canonical: https://bigchange.ai/blog/aws-uaef-agent-evaluation-framework
AI-generated conceptual illustration for BIG CHANGE
Amazon Web Services introduced the open-source Universal Agent Evaluation Framework (UAEF) on November 11.
## The big change
- UAEF converts supported agent records into a common format before scoring them, allowing comparisons across frameworks.
- Developers must choose tests that reflect the intended use. NIST recommends documenting the risks that are not measured as well as those that are, so gaps remain visible.
- Automated judgments depend on their method and dataset. Research on information retrieval shows why agreement with human reviewers in one setting should not be assumed to transfer to another.
## From an agent run to a score
An AI agent can respond to a request by calling software tools or handing work to another agent. Two systems may produce a similar answer while taking very different routes to it.
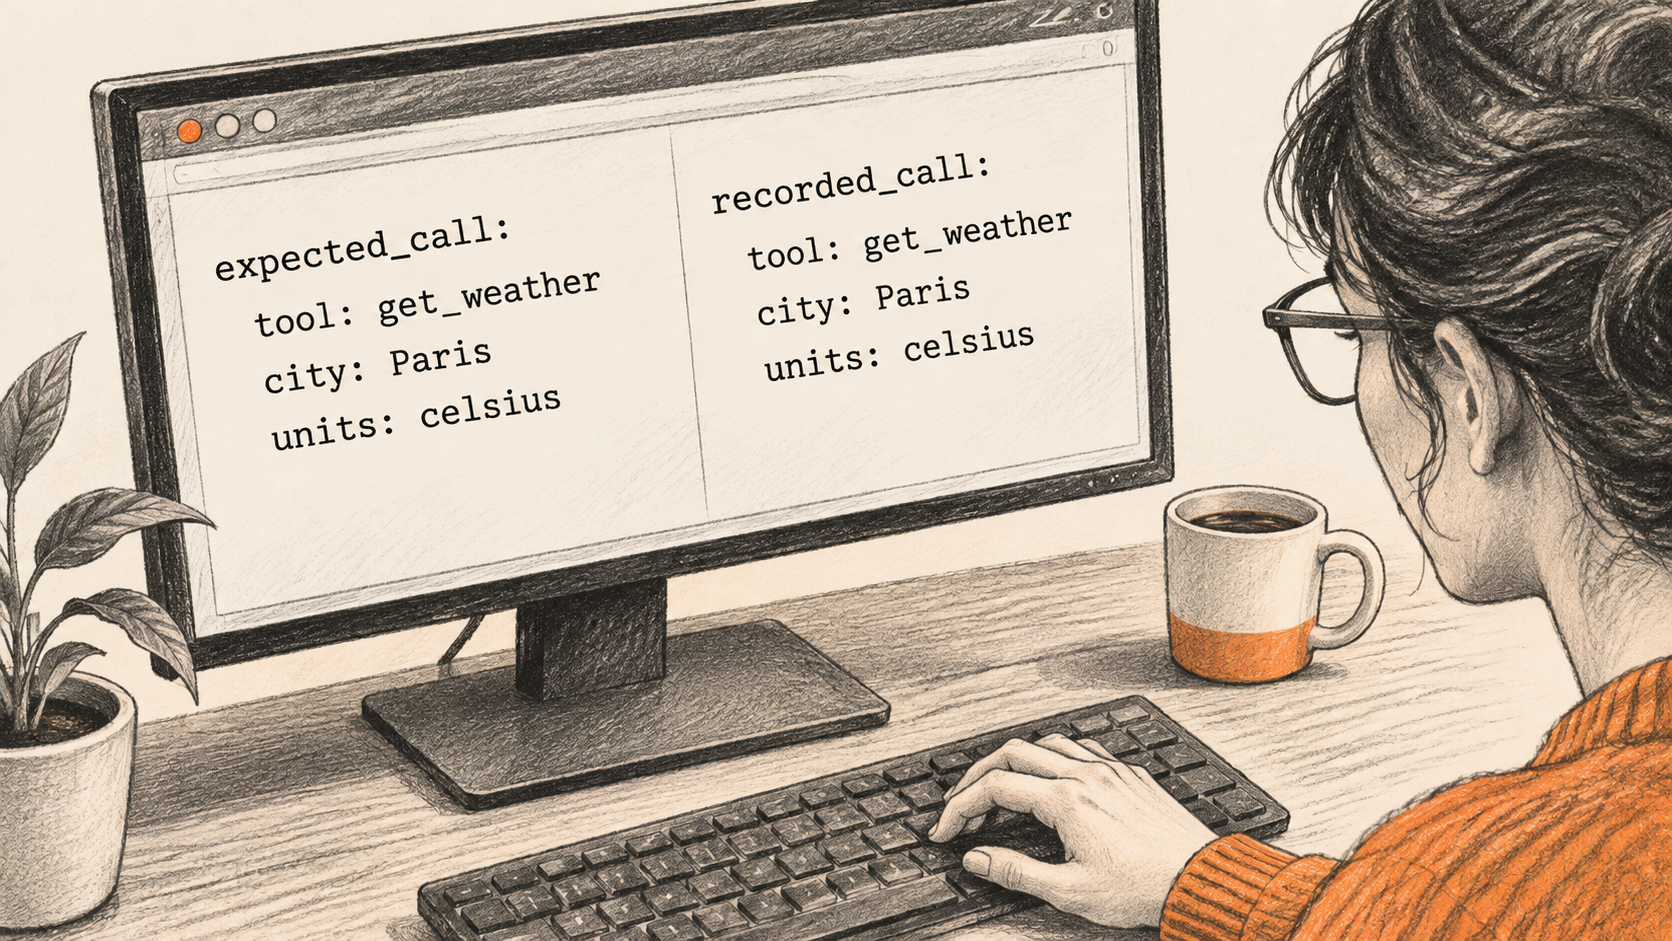
[AWS says](https://aws.amazon.com/blogs/machine-learning/uaef-a-framework-agnostic-system-for-closed-loop-evaluation-of-ai-agents/) adapters convert records into an AgentTrace: a shared record of messages, tool calls and handoffs. Scores use calculations or Bedrock model judgments. In AWS’s travel-booking example, tests can compare tool selection, order and arguments against expected calls supplied by developers.
That example illustrates a distinction between checking an answer and checking the steps behind it. An itinerary can sound plausible without demonstrating that the intended booking process was followed. This is an explanation of the test’s purpose, not a measured result.
The [repository](https://github.com/awslabs/uaef) offers Python and deployable-service paths under Apache 2.0. Optional persistence puts metadata in DynamoDB and results in S3; retained service resources can keep costing money after stack deletion. AWS warns that judge scores must not gate security controls.
BIG CHANGE has not independently tested the software. Before retaining test records, teams should decide who may access them and when to delete them.
## Choosing evidence for a release
[NIST’s measurement guidance](https://airc.nist.gov/airmf-resources/playbook/measure/) says the purpose, audience and needs of an evaluation should determine what is measured. It recommends defining acceptable performance limits and documenting metric choices, including measures considered but not used. That changes the release question from “did the average score rise?” to “did the system meet the limits chosen for this use?”
A test set also needs to represent the work the system will face. Leaving out an important situation leaves a gap in the evidence; repeating the same scoring procedure does not fill that gap. NIST recommends assessing performance before and after deployment, including emerging risks.
A separate [NIST research abstract](https://www.nist.gov/publications/llm-assisted-relevance-assessments) reports that language-model assessments can be biased despite some agreement with humans. A successful model or prompt on one dataset need not work similarly on another task. That research concerns ranking documents for relevance, not UAEF or a test of booking agents.
[NIST’s ARIA planning manual](https://www.nist.gov/publications/aria-evaluation-planning-manual-elements-aria-style-ai-evaluations) describes combining model testing, red teaming and user testing. These are complementary sources of evidence: checking model outputs is only one part of understanding an application in use. For a team preparing a release, the remaining work is to specify the failures that matter and investigate them, rather than treat a single score as permission to ship.
## Sources
- [AWS UAEF](https://aws.amazon.com/blogs/machine-learning/uaef-a-framework-agnostic-system-for-closed-loop-evaluation-of-ai-agents/) — Release and implementation.
- [NIST AI RMF measurement guidance](https://airc.nist.gov/airmf-resources/playbook/measure/) — Evaluation and representative data.
- [NIST research on relevance assessments](https://www.nist.gov/publications/llm-assisted-relevance-assessments) — Limits of model judgments in information retrieval.
- [NIST ARIA evaluation planning](https://www.nist.gov/publications/aria-evaluation-planning-manual-elements-aria-style-ai-evaluations) — Complementary evaluation approaches.
The BIG CHANGE newsletter
The big picture. At your pace.
Recent stories on AI and robotics, the shifts worth watching and practical ideas to use. Choose a daily briefing, weekly digest or monthly perspective.
Next scheduled send (UTC): . Your first edition arrives at the next scheduled send after you confirm.
Your privacy, your choice.
Necessary storage supports site security and remembers your choices. Optional Google Analytics stays off until you allow it. You can read every story with necessary storage only. Privacy details