Graphon Labs has raised $35 million in a Series A round to develop memory infrastructure for AI agents.
The big change
- What happened: RRE Ventures led the round announced on November 10. Graphon plans to expand enterprise, developer and on-device offerings; funding does not establish that every product is ready.
- Why memory matters: An assistant may need older emails and images to answer a new question. Retrieving relevant records gives the model evidence to examine, but finding a record and interpreting it correctly are separate challenges.
- What to watch: Long-conversation tests examine whether a system recalls events and their timing. A benchmark score describes performance on those tasks, so buyers should also check answers against the records and conditions of their own work.
How records become an answer
The ATM-Bench researchers divide memory systems into three stages. First, information is processed into a searchable store. A query then retrieves relevant items, which an answer model examines. An error can enter when evidence is selected or when the model reasons over it.
Graphon says it extracts people, places and things from files, links their relationships in a graph, and retrieves a connected portion to help answer a question.
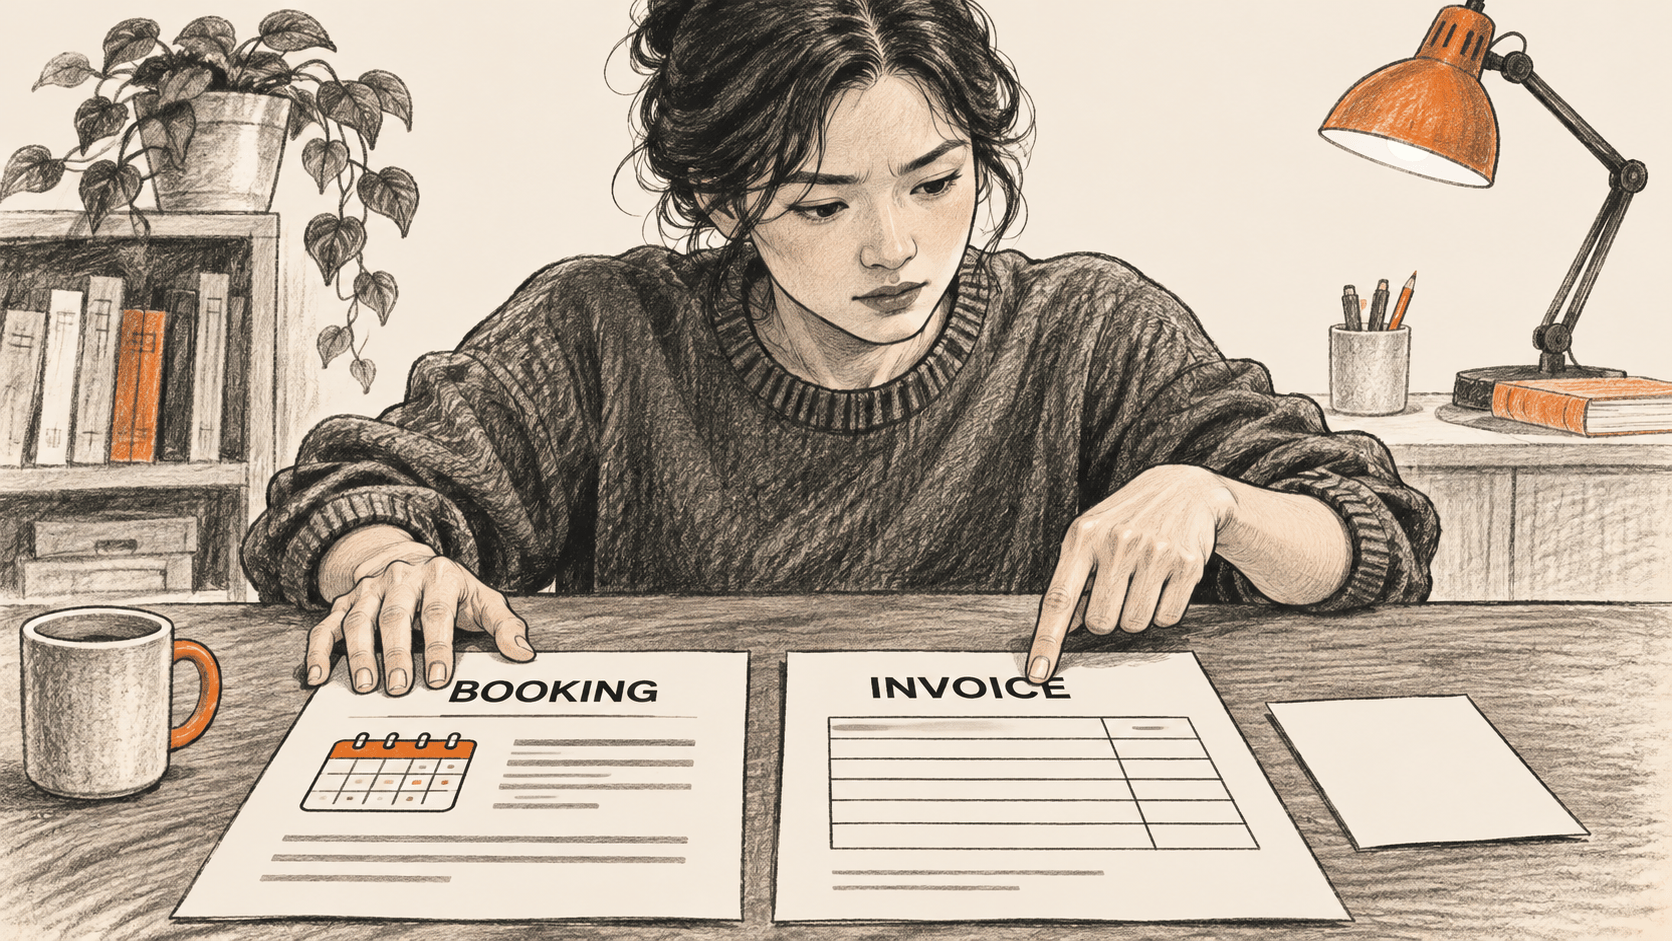
The ATM-Bench paper gives a concrete example: calculating hotel expenses from booking records and final invoices. In one reported failure, the answer model received both records but used the outdated booking information. Retrieving the right evidence therefore did not ensure the right answer.
ATM-Bench spans roughly four years of personal images, videos and emails. This is a personal-memory test, not a complete enterprise workload.
What a benchmark can show
Graphon reports accuracy of 93.9% on LoCoMo and 81.7% on ATM-Bench. BIG CHANGE has not verified those company-reported results.
The original LoCoMo researchers created long conversations using simulated speakers with personas and timelines, then had human annotators correct inconsistencies. Conversations average roughly 600 turns and can span up to 32 sessions. The tasks include questions about past events, summaries and responses involving images.
This makes the chronology part of the challenge. Recalling that an event happened is not always enough: a system must place it in the right speaker's history and understand its relationship to other events. The paper reports that models could recover facts yet struggle with temporal and causal understanding.
The ATM-Bench leaderboard says Graphon's submission uses its own raw-media pipeline while retaining supplied captions and other metadata. That setup matters when interpreting comparisons; the listing is submitted evidence, not a production audit.
What customers have established
Graphon's announcement describes enterprise deployments, but the 49ers discuss exploring uses and Hitachi Rail describes an evaluation. Those statements do not establish completed production deployment for either named use.
The company lists customer-managed deployment among its enterprise options.
Buyers can test representative questions and check the answers against their own records before relying on the system.
Before connecting internal records, decide who may store and retrieve them and how corrections or removals will be handled. Those are purchasing questions, not controls independently verified in Graphon's product.