Liquid AI released d1-ultra on October 15 as a hosted model for questions with a defined set of answers. A developer sends text, images or both, specifies the questions, and receives probabilities rather than a written response. The interface makes the model relevant to routing, classification and image checks, but its probabilities still need to be judged against the results of the particular task it will handle.
The big change
- What changed: Liquid now offers its larger decision model through an API. A team can ask several defined questions about the same text or image in one request and receive a probability for each answer, without paying for generated output tokens.
- Why it matters: For developers building routing or inspection software, the useful output is often a label, score or yes/no estimate. The fixed answer types make that result directly available to downstream rules. Liquid's billing counts the input again for every question, so adding checks to one image also adds cost.
- What to watch: The decision for an operator is where to set thresholds and when to send uncertain cases to a person. Independent benchmark results can inform model selection, but a score across general tasks cannot set a reliable threshold for a company's own images, labels or error costs.
What the API returns
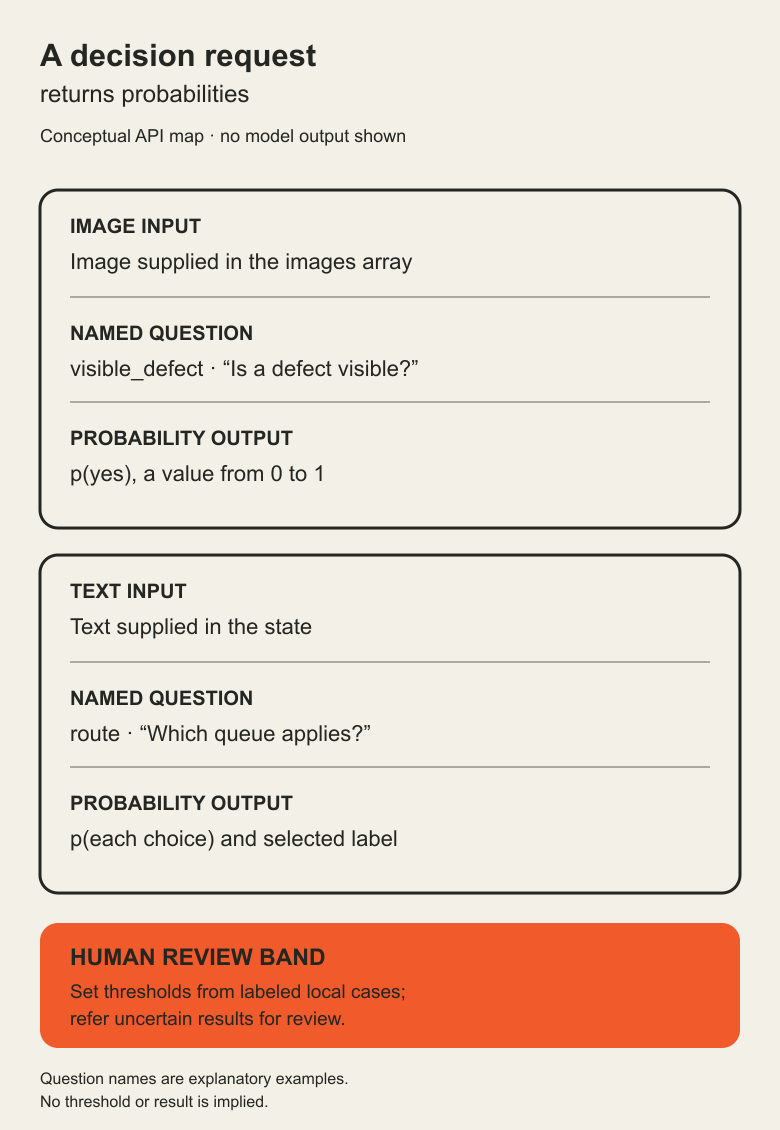
Liquid's current decision-model documentation lists d1-ultra alongside d1 on the same POST /decisions/v1/systemone endpoint. The request names the model, supplies a state containing the material to assess, and gives one or more named questions. Image requests add an images array. The docs say a Liquid Console account, organization and API key are needed for direct access. They also list OpenRouter and Vercel AI Gateway as providers; Liquid's October 15 launch post had described those two routes as forthcoming, so its availability sentence is already older than the current docs.
There are three question types. A noul question returns a number from zero to one for a yes answer. A choice question returns a selected label and probabilities for the defined labels. A score question returns a probability-weighted position on an ordered rubric and the probabilities for its levels. The response's answers object is keyed by question name. Its usage reports total input tokens and zero output tokens. A number such as 0.85 is the model's estimate for the question as framed, not a verified observation that a defect or other condition exists.
The documentation's circuit-board example asks whether an image shows a visible defect. Liquid also illustrates code that would reject an image above one probability threshold, pass it below another and refer the middle range for manual review. Those thresholds are part of its example, not independently established operating points. A deployment would need labeled examples from its own task to measure errors and choose what to review.
The price of repeated questions
Liquid's pricing page lists d1-ultra at $0.042 per million input tokens, with a $0 output-token rate. The API docs say each question is billed for its own text and every supplied image, even when several questions share one request. An image is counted at 1.5 tokens for each 32-by-32-pixel patch, with patch counts rounded up per image.
For a 1,024-by-1,024-pixel image, Liquid counts 1,536 image input tokens per question. At the listed d1-ultra rate, that image portion is about $0.0000645 for one question or $0.000129 for two. The full charge is higher because the state and question text also consume tokens. This calculation describes the published meter, not an observed bill or a tested image result. The docs limit image requests to eight images, a JSON body under 4.5 MB and 10,000 image patches across the request.
What the comparisons show
Liquid says it compared d1-ultra with its earlier d1 and Jev 1.14 across 112 evaluations and found stronger accuracy and calibration. It also says d1-ultra leads other decision models on the Artificial Analysis Decision Index by at least eight points. The first comparison is Liquid's own analysis. Its launch post does not supply enough task-by-task detail in the text to infer how the model would perform on a reader's inspection or routing data.
Artificial Analysis does list d1-ultra in its Decision Index interface and says it conducts the evaluations independently. Its version 1.0 methodology gives equal weight to four tests: knowledge and abstention, text-only multiple-choice reasoning, tool-call selection, and safety classification. For a yes/no question it treats a probability of at least 0.5 as yes; for a choice it scores the highest-probability option. The published page also describes calibration and cost measures. Its accessible text does not expose a numerical d1-ultra index score, so Liquid's eight-point lead remains a vendor-stated figure here.
This independent evaluation gives buyers a broader check than Liquid's launch examples. It does not test a specific factory camera, claims process or support queue. A pilot can compare labeled local cases, false positives, false negatives, review volume and the actual billed input tokens before a probability becomes an operational decision.
Sources & further reading
- Liquid AI's October 15 d1-ultra announcement gives the release date, model description, company comparisons and image billing example. Its benchmark claims are attributed to Liquid.
- Liquid's decision-model API documentation specifies the current endpoint, question and answer shapes, image limits and per-question billing. The examples document an interface; BIG CHANGE did not run them.
- Liquid's pricing page lists the current published US-dollar input and output rates.
- Artificial Analysis's Decision Index and version 1.0 methodology establish the independent test scope and d1-ultra's inclusion. The accessible page text does not provide its numerical score.
- BIG CHANGE's “Jev study: cheaper decisions, fewer mobile tasks completed” examines cost and task completion in a different mobile-agent decision workflow. Its results do not measure d1-ultra.
- Our “Liquid AI’s LFM2.5 24B model gives local agent builders more serving choices” covers downloadable generative checkpoints, a separate release from this hosted decision model.