Ai2 announced XYBench's release on November 13; its research paper dates to September 6. The benchmark tests responses to misguided requests. EMNLP lists it as Best Resource Paper.
The big change
- A person can ask for help with an attempted solution while leaving the actual problem unexplained. A literal answer may therefore help with the wrong task.
- XYBench scores both proposed solutions and the answer's emphasis. Mentioning an alternative is different from making it the main recommendation.
- Automated judging needs its own evaluation. Earlier research shows that a judge can favor an answer's presentation rather than its usefulness.
Start with the goal
The longstanding community explanation of the XY problem describes someone trying to achieve X, assuming method Y will work, then asking only about Y. The helper can spend time solving the requested subproblem without discovering that the method was unsuitable.
Its filename example makes the distinction concrete. A user asks for the last three characters of a filename because they want its extension. Extracting three characters answers the literal question, but extensions need not have three characters. Asking what the user needs the text for changes the advice.
The same guide recommends explaining the broader situation and why other approaches were ruled out. That context helps a helper distinguish a genuine requirement from an assumption that can be reconsidered.
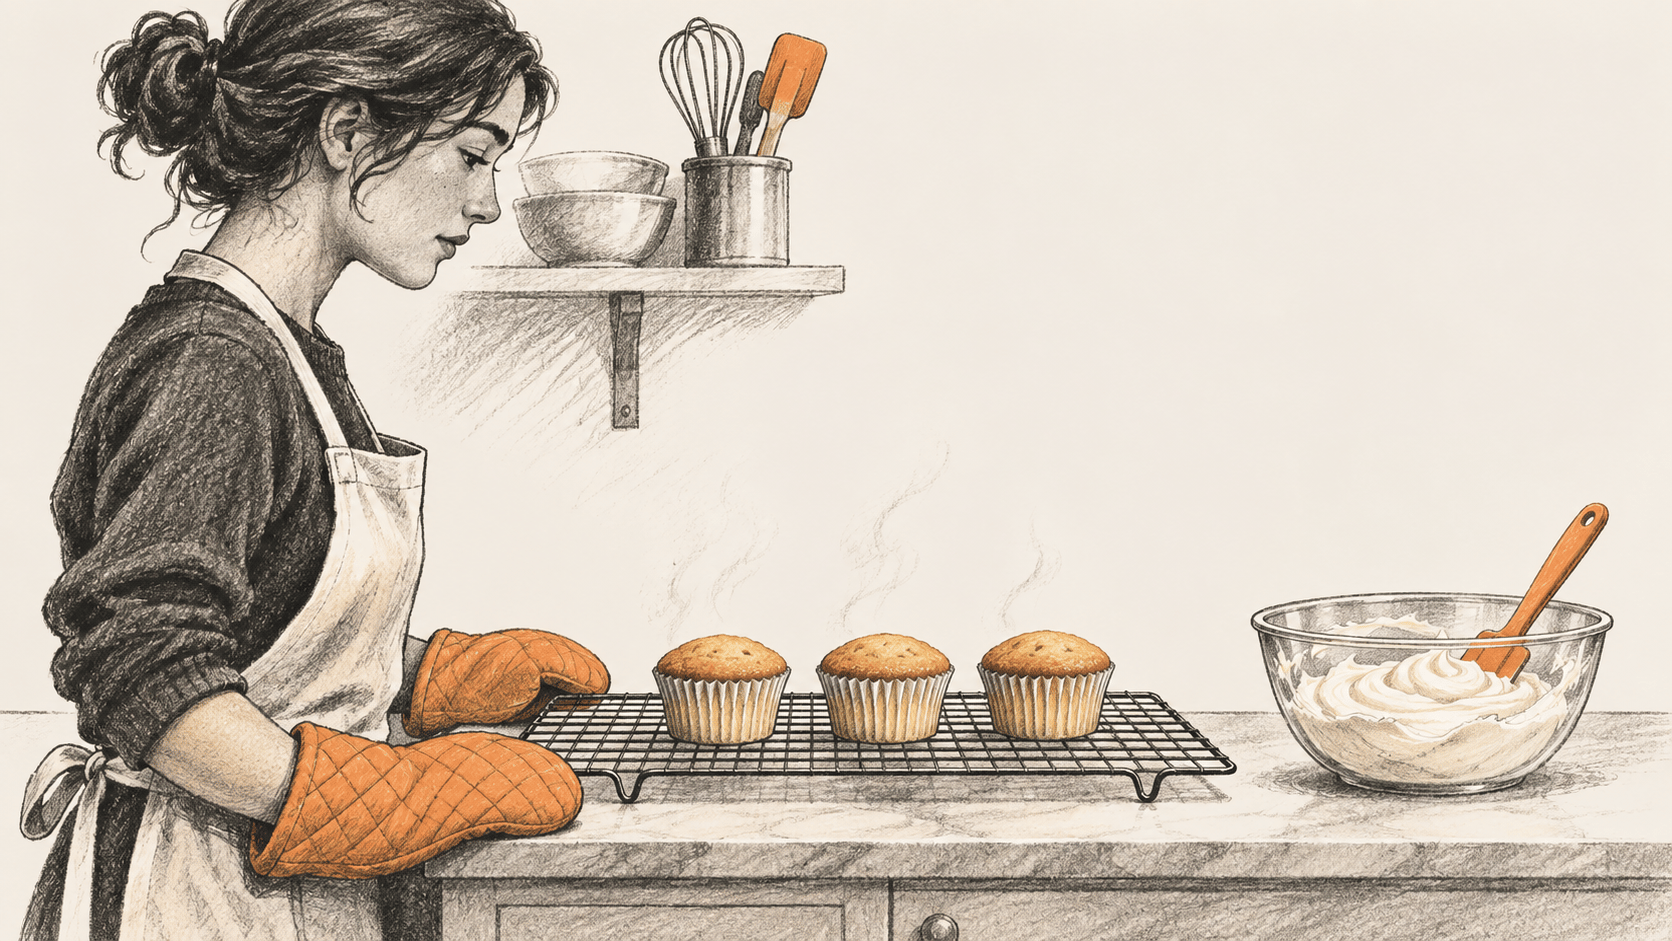
Ai2's example asks about frosting when cupcakes need cooling.
What XYBench measured
The paper reports over 8,000 English queries, mostly synthetic. Human comparisons use selected existing answers, with none for WikiHow.
For 1,557 Stack Overflow questions, five tested models mentioned goal-oriented solutions in 59–71% of single-turn answers, but emphasized them in 35–41%.
Claude Sonnet 4.5 judged responses; two authors checked 500: 100 Stack Overflow and 400 WikiHow. Emphasis agreement was 74.2–79.8%, not overall accuracy. These are procedural tasks, not evidence about every conversation.
The judge is part of the test
A separate 2023 study of LLM judges examined how automated ratings compare with human preferences. It identified position bias, where answer order influences a comparison, and verbosity bias, where a longer answer can receive undue credit. It also found errors in judging reasoning.
These are methodological cautions, not findings that those biases explain the XYBench scores. They show why a rating procedure needs checking rather than becoming ground truth merely because a model produced it. An evaluator should distinguish the response being tested from the mechanism assigning its score.
That earlier study treats capability benchmarks and preference-based evaluation as complementary. One test can assess a narrow skill while another examines whether people find an answer useful; neither automatically substitutes for the other.
XYBench code is available; dataset files require login and conditions, under CC BY-NC-SA 3.0.