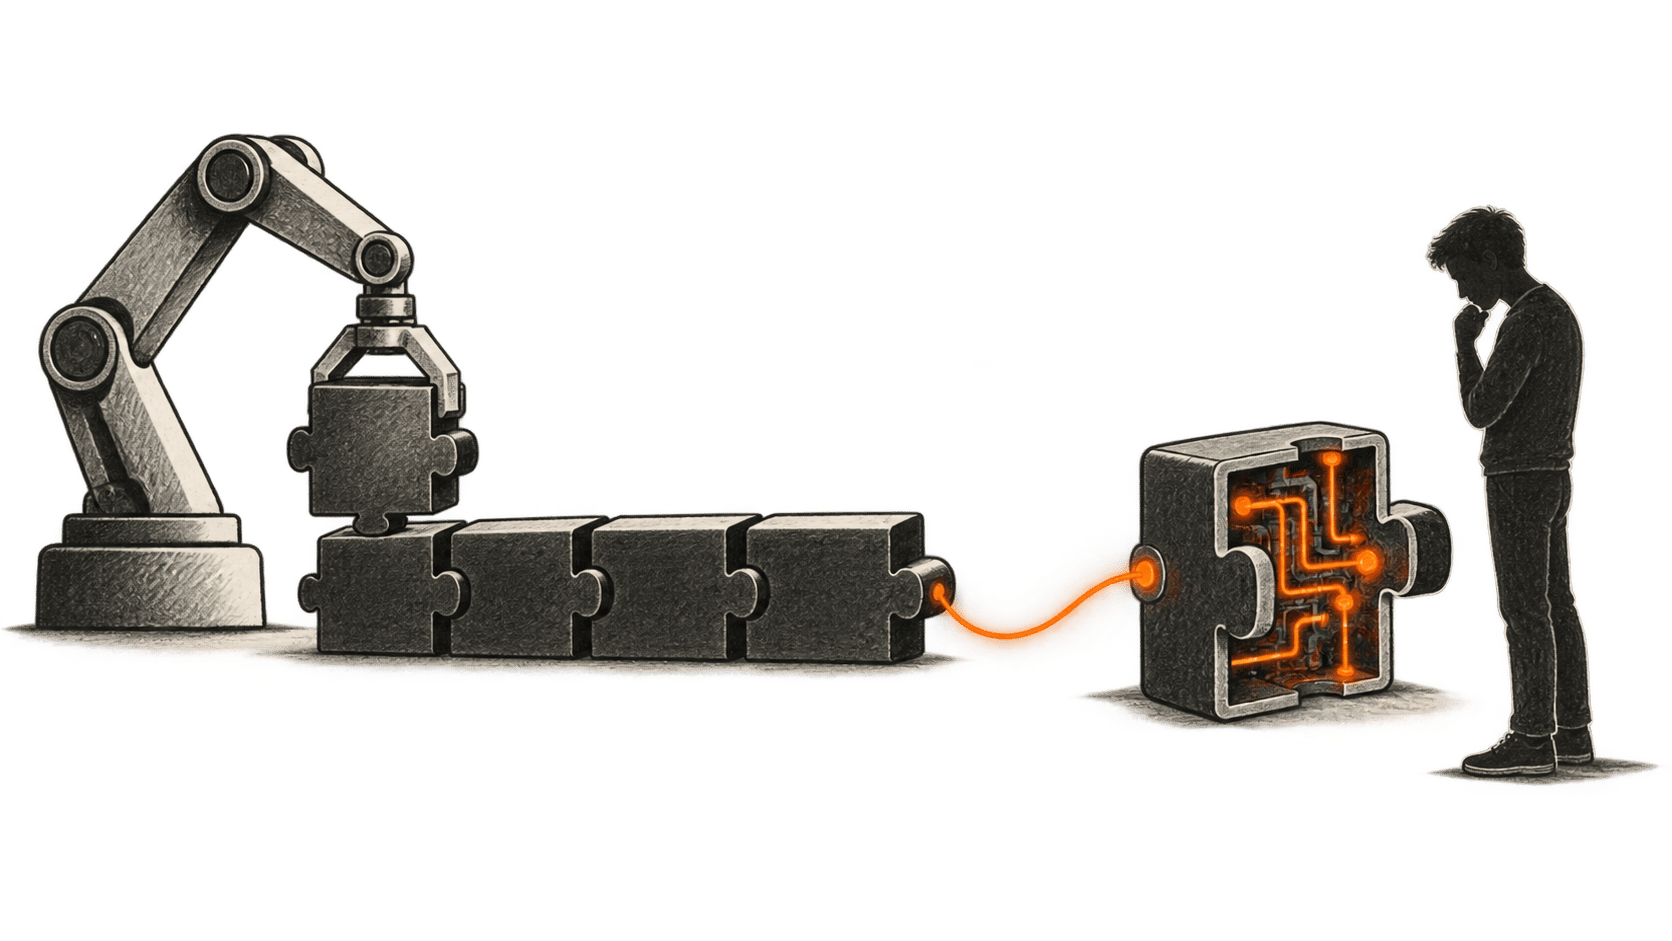
A junior developer can ask an AI assistant to use an unfamiliar library, get working code, and move on. The feature may be ready before the developer understands why it works. That matters the next time the code fails, the requirements change, or someone has to decide whether the assistant's fix is safe.
Software engineer Alexandru Nedelcu raised this worry in a September 22 essay. He argues that developers build judgment by reading code, making choices and living with mistakes. His prediction that some firms will advertise policies against AI is an opinion, not an observed industry shift. A separate experiment published in January gives the learning question a narrower, testable form: what did programmers understand immediately after completing a task with AI help? Anthropic's research account
The big change
- What changed: AI makes it easier to submit finished software without having worked through its logic. It can supply an implementation before a newcomer has practiced the decisions needed to explain or repair it.
- Why it matters: Managers may gain output today while weakening the path by which junior staff become the people who can diagnose tomorrow's failures. The risk is most acute when a task uses unfamiliar concepts; help on familiar work can still be valuable.
- What to watch: Teams may start treating learning as part of delivery, setting aside time to explain, diagnose and adapt AI-assisted work. If they do, hiring exercises and coding products may reward demonstrated understanding alongside speed.
A completed task and a learned skill are different results
In a randomized study of 52 programmers, participants used an unfamiliar Python library called Trio to complete two coding tasks. Half had an AI assistant available in the coding environment; half did not. They knew a quiz would follow. The quiz tested concepts, code reading and debugging shortly after the work.
The AI group averaged 50%, compared with 67% for the group working without AI: a 17-percentage-point difference, not a 17% relative decline. The largest gap was on debugging questions. The AI group finished about two minutes faster on average, but that time difference was not statistically significant. These are results for a brief encounter with one library and an immediate test, not a measurement of developers' careers or the quality of a production system. The researchers' results and limits
The researchers also watched how participants used the assistant. Some largely delegated code and debugging; others asked for explanations or worked through concepts themselves. The more engaged patterns tended to score better, but these small groups were identified after the fact. Participants were randomized to access to AI, not to a particular way of talking to it. Asking for an explanation may help a learner, but this study cannot prove that one prompt or workflow prevents the learning gap. The paper's interaction analysis
An error is often the moment a newcomer learns what a library assumes. If the assistant absorbs both the initial implementation and the repair, the developer may see fewer of those assumptions. That is one possible explanation for the debugging gap.
Speed still counts, and the task changes the answer
AI assistance has also sped up coding under different conditions. In a controlled GitHub Copilot experiment, 95 professional freelancers were assigned to build a JavaScript HTTP server. Among those who finished, the Copilot group completed the task in about 71 minutes on average, compared with about 161 minutes in the control group, a 55.8% reduction in completion time. The researchers did not test what those programmers learned afterward. The task was a bounded implementation, not an introduction to an unfamiliar library followed by a comprehension quiz.
Both findings can be useful to a manager. If an experienced developer uses AI to clear repetitive work, saved time may be real. When the job is to learn a new system, faster output and stronger understanding need separate checks. A blanket AI ban would throw away potential gains without answering how people learn to oversee the work.
Nedelcu's essay goes further than the experiment. He argues that maintainability becomes visible over months or years and that experience grows through responsibility for mistakes. The study does not measure long-term maintainability or show that AI users stop learning altogether. His useful challenge is organizational: if a team increasingly delegates the practice work, where will its future troubleshooters get that practice? Nedelcu's essay
Give the learner something to prove after the code runs
One practical response is to give a newcomer an AI-assisted task and then ask for a short independent check before treating the work as a learning success. This is our proposed exercise, not an intervention tested by either study:
- Explain: Without asking the assistant, describe why the unfamiliar part of the code works, what it assumes, and what would make it fail. A senior engineer can ask one follow-up question tied to the actual change.
- Diagnose: Introduce a small, realistic failure in a safe test branch. Have the learner locate the cause and say which observation ruled out a tempting wrong fix. The point is reasoning, not memorizing a command.
- Adapt: Change a requirement, then ask the learner to revise the implementation and its tests. They may use AI, but they should be able to defend the new behavior and name what they still need to verify.
For example, after an assistant writes a new asynchronous operation, a reviewer might ask what happens when it is cancelled halfway through. The developer should be able to trace the path and test a changed requirement. A code review alone might catch a defect while leaving the learner unable to handle the next one. The proposed check asks whether knowledge travels with the delivered code.
This need not turn every routine ticket into an exam. A team could reserve the exercise for unfamiliar libraries, recurring failure modes or work a junior colleague is expected to own later. It takes paid time and a reviewer who knows the system. If management counts only merged tasks and time saved, those costs may be the first things cut. That would make the training problem harder even if today's output rises.
The apprenticeship question reaches hiring and product design
Junior roles have often mixed delivery with supervised practice. AI changes that bargain when a candidate can show an impressive finished feature without showing how they reasoned through it. Employers could ask candidates to explain and modify a small piece of work rather than treating a polished repository as proof of independent skill. That is a proposed hiring response, not evidence of a current hiring trend. It should test the abilities the role actually needs, not demand that every applicant work without tools.
Coding products face a related choice. An assistant can optimize for a quick answer, or it can make it easier to inspect assumptions, ask conceptual questions and try a change before revealing a solution. The study's observed interaction patterns make the second design worth trying, though they do not establish that a specific interface teaches better. For employers, the corresponding purchase question is whether a tool helps staff learn to review and change its output, not only how much code it generates.
The short quiz cannot tell us who will become an expert in five years. It does show why an accepted implementation is a poor substitute for evidence of understanding on an unfamiliar task. Teams that want both automation and a capable next generation have to make room for practice and check what people can do when the answer changes.