Mistral opened a Public Preview of Large 4 on October 6, 2026. Developers can call its hosted API with the model ID mistral-large-4. The model card describes it as open-weight, while Mistral's company update says a full release is planned for later in October. We did not verify downloadable weights for this preview. This guide follows Mistral's documentation; BIG CHANGE has not sent an API request or measured the model's output.
The big change
- What changed: A new Mistral flagship is available to developers through a priced API preview. Its documented 1 million-token context and vision encoder widen the kinds of material an application can send, though this walkthrough uses text only.
- Why it matters: A team can evaluate Large 4 through the hosted chat interface today. The published token rates make a small trial's variable cost calculable in advance. Output quality and latency still need measurement in the team's own application.
- What to watch: Mistral says a full release is planned for later this month. Teams interested in self-deployment will need to verify whether downloadable weights become available and under what terms. The current Public Preview can receive silent updates and has no guaranteed route to general availability, so an integration decision also depends on lifecycle tolerance.
Send a text request
Mistral's API quickstart says to create a Studio account, activate payments to enable API keys, and use a key for the chat endpoint. It does not state a minimum purchase in those instructions. Store the key as MISTRAL_API_KEY in your environment. The model card identifies the preview model as mistral-large-4; the quickstart's older mistral-large-latest example names a different alias. Mistral's lifecycle policy says Public Preview models do not get -latest aliases.
The request below uses the documented chat completions endpoint. Its small task is to extract two facts from the model card text. Replace the prompt with material from your application after checking its accuracy and permissions.
curl https://api.mistral.ai/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $MISTRAL_API_KEY" \
  -d '{
    "model": "mistral-large-4",
    "messages": [
      {
        "role": "user",
        "content": "Extract the model name and context size from this text: Mistral Large 4. Context: 1M tokens. Answer in one sentence."
      }
    ]
  }'
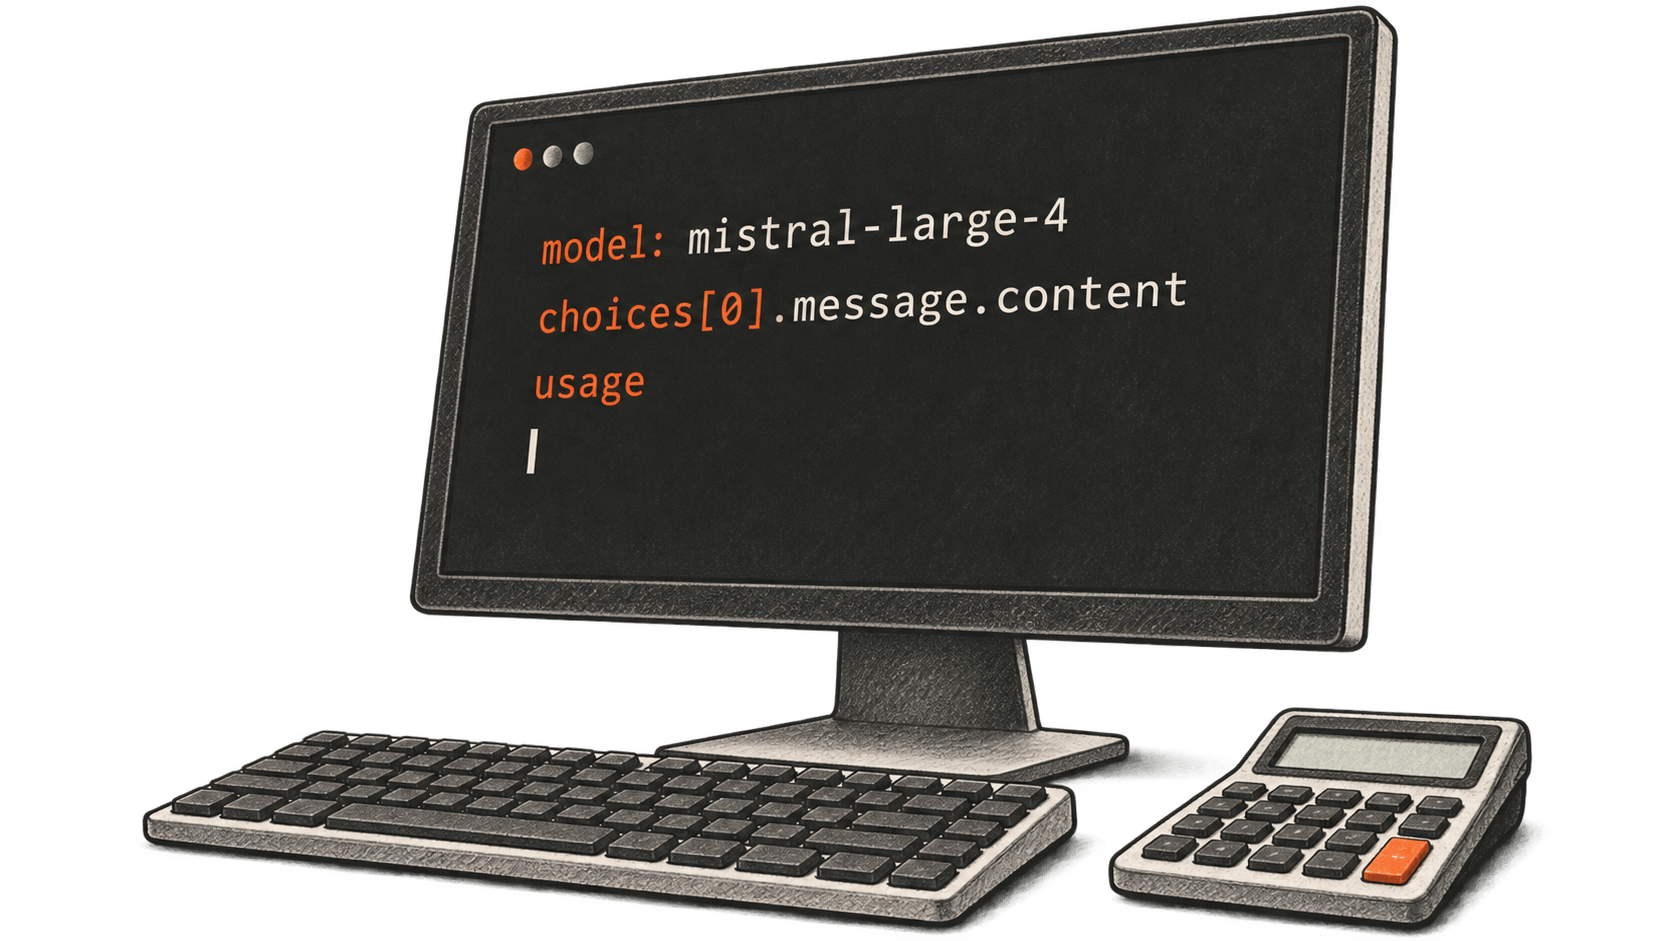
The endpoint takes a model string and a messages array. Here the sole message has the user role and text content. On a successful, ordinary chat completion, Mistral documents a response with choices; the generated text is in choices[0].message.content. The response also contains model and usage. You should expect an answer identifying Mistral Large 4 and its 1 million-token context, but its exact wording is generated and has not been checked by BIG CHANGE. Inspect the returned usage for the actual token counts rather than treating the prompt's visible words as tokens.
The model card lists structured outputs, function calling, document Q&A, chat completions, batching, agents and built-in tools. It describes a vision encoder, but this text request does not establish an image payload format or test visual understanding. Consult the relevant feature documentation before adding files, images or tools to an application.
Estimate the variable charge
As listed on the October 6 model card, standard input costs $0.68 per million tokens, cached input $0.07 per million, and output $2.09 per million. For an illustrative request with 1,000 uncached input tokens and 200 output tokens, the token charge is (1,000 × $0.68 + 200 × $2.09) ÷ 1,000,000 = $0.001098. Those token counts are assumptions for arithmetic, not a measured run of the request above. Account plan terms and any other charges are outside this example.
The 1 million-token context is the maximum space for input and output combined. Mistral's known limitations say an overlong request returns 400 Bad Request. The platform also applies organization rate limits that vary by plan and model, returning 429 Too Many Requests when exceeded. Check your account's available models and limits before building around the preview.
Mistral's lifecycle policy defines Public Preview as near-final and subject to silent updates. It gives no guaranteed path to general availability and a one-month deprecation notice. Keep the model ID explicit in your integration, record the returned model and token usage for each request, and rerun your own application checks when the preview changes. These are practical precautions drawn from the published lifecycle terms, not results from BIG CHANGE testing.
Sources & further reading
- Mistral Large 4 model card, dated October 6, 2026. Gives the
mistral-large-4ID, Public Preview Open v26.10 status, 1 million-token context, listed features and current token prices. - Mistral's company update, October 6, 2026, says the model is available to preview now and a full release is planned for later in the month. Its launch announcement was unavailable to our retrieval tool. We did not verify a downloadable weight file or an exact weight-release date.
- API quickstart and chat endpoint reference. Explain payment activation for API keys, the request fields and the response structure. The code above adapts their general chat example to the Large 4 model ID.
- Model lifecycle policy and known limitations. Explain preview updates, retirement notice, context errors and rate limits.