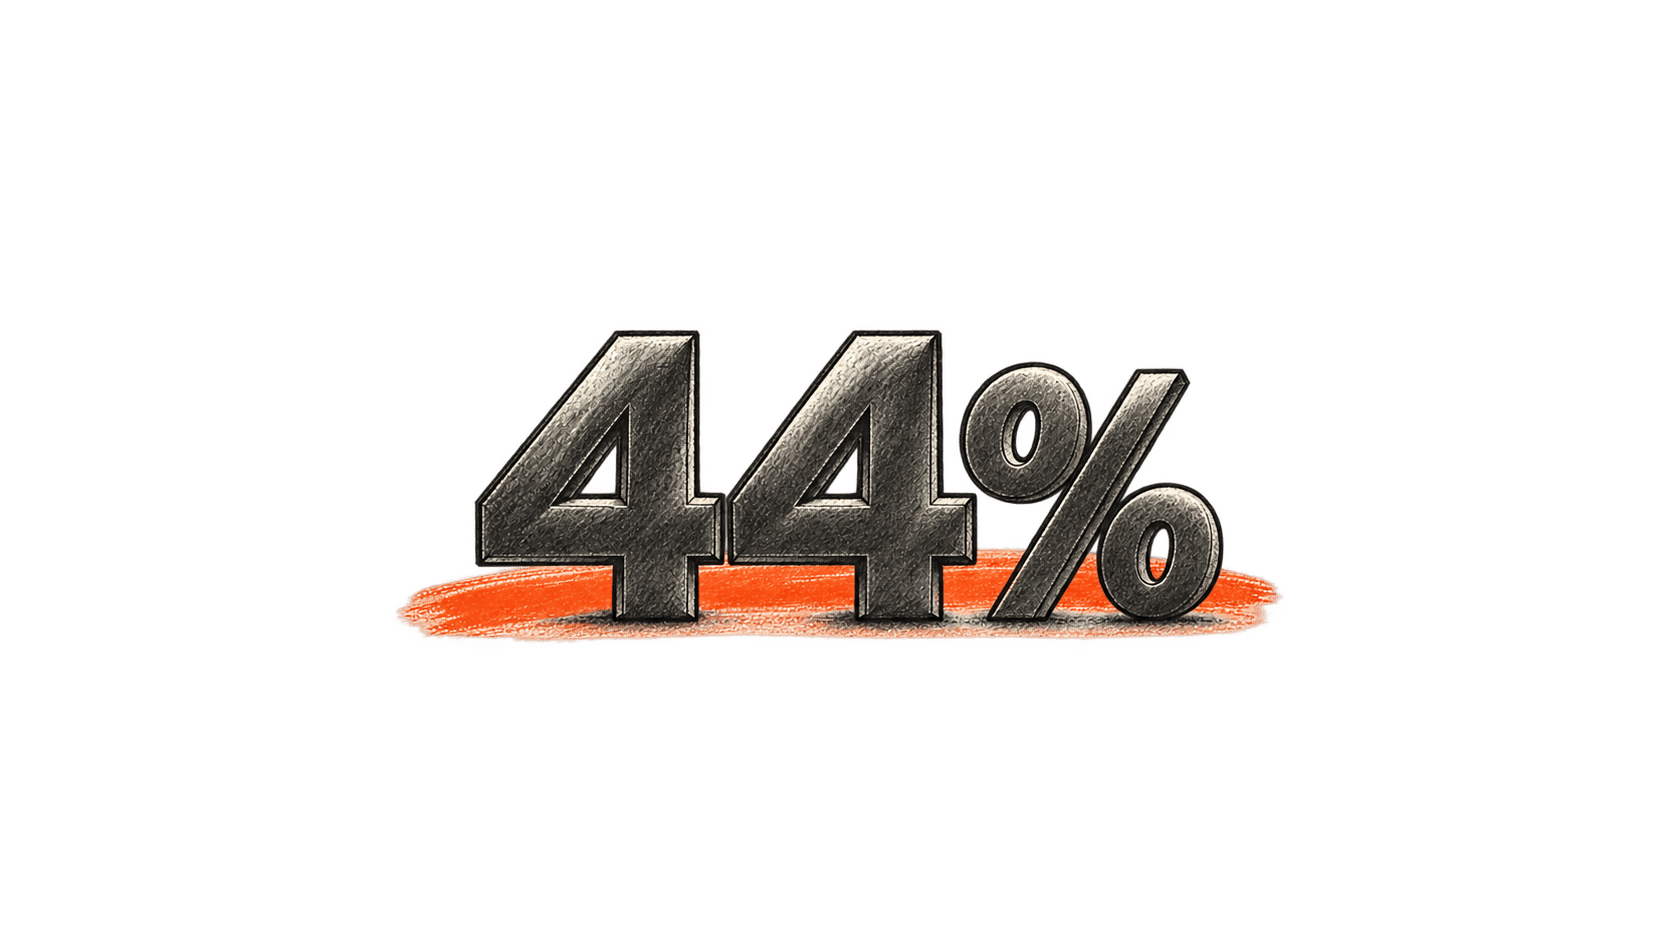THE WORLD IS NOT STANDING STILL.RSS
BIG CHANGE.
BIG CHANGE, one tap away

Make room for the big picture.

Add BIG CHANGE to your home screen or desktop. It opens in its own window, with the latest stories when you’re online.

iPhone & iPad
Open bigchange.ai in Safari. Tap Share, then Add to Home Screen. Turn on Open as Web App if shown, then tap Add.
Android
Open bigchange.ai in Chrome. In the browser menu, choose Install app or Add to Home screen.
Desktop
In Chrome or Edge, use the install icon in the address bar or the browser’s app menu. In Safari on Mac, choose File → Add to Dock.
All briefings

Follow the change ·

The day,
in perspective.

What happened in AI and robotics — and the change behind it. A reading path through 32 stories from BIG CHANGE.

Ordered using RADAR attention, story opens and likes. Excerpts from our published reporting; open a story for the full context and sources. Dates in UTC.

Original story: news

Treasury proposes broader AI investment prohibition

Treasury proposes a broader AI investment prohibition. The current outbound investment rule remains in force.

The big change

What changed: The draft treats development of any defined “super intelligence” system as prohibited technology. Current rules also have a notifiable AI category based on end use and training compute.

Why it matters: Agent harnesses that extend third-party models can count as development. The proposed prohibition still depends on the investor, transaction, foreign person and technology involved. Strictly internal, non-commercial use of an off-the-shelf system does not count as development solely on that basis.

What to watch: Treasury seeks comment on the AI definition. The final rule will set an effective date; Part 850 obligations remain operative.
Read the full story
—
Back to the briefing
Original story: analysis

PaperFormalizer asks authors what Lean should prove

PaperFormalizer pairs author review with Lean proofs of revised claims.

The big change

What changed: Authors review substantive repairs before Lean proofs. They can reject or redirect repairs, then compare the checked statement with their intended claim.

Why it matters: The treatment-effects study asks about a causal effect under extreme conditions. A proof under stronger assumptions can establish a revised result while leaving the printed claim unsupported. Researchers need to judge whether those assumptions fit the data and whether the revised result still answers their question.

What to watch: The meaningful comparison is among the printed claim, the revised conditions and the Lean statement that was checked. A valid derivation establishes a mathematical implication under its premises; it cannot supply evidence that the premises hold in the research setting.

Read the full story
—
Back to the briefing
Original story: analysis

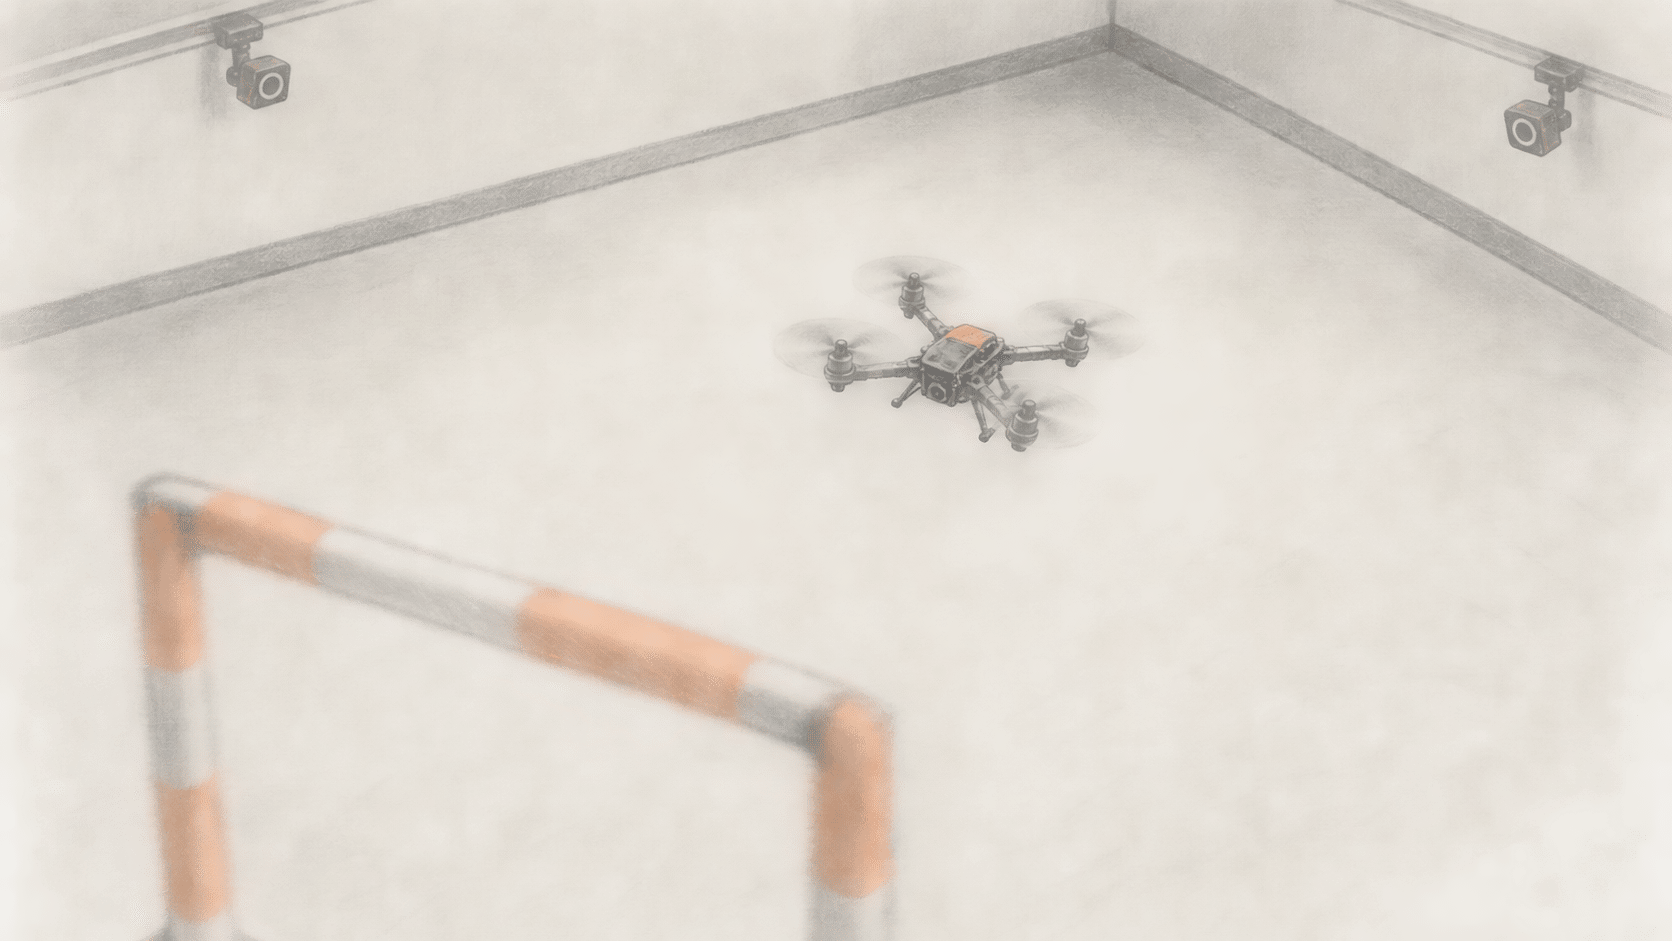
DiffDreamer gate physics

Simulated gates, externally tracked flights.

The big change

What changed: DiffDreamer advances a learned gate forecast and explicit aircraft physics with the same command. One policy weighs predicted opening motion against vehicle response.

Why it matters: Differentiable physics shows how changing an input changes later simulated motion. Its gradients give a learner a direction for adjusting continuous behavior, whereas a final success score alone says little about which command caused the change.

What to watch: The gate-count advantage is simulated. Indoor flights used external positions, showing physical control with that support while leaving onboard gate estimation outside the demonstrated result.

Read the full story
—
Back to the briefing
Original story: analysis

Skin-lesion test separates diagnosis accuracy from discharge risk

CNN led diagnosis; its preset discharge rule missed more melanomas.

The big change

What changed: Inception v3 led diagnosis but its preset rule recommended more melanoma discharges. Researchers must evaluate discharge decisions separately.

Why it matters: For clinical triage, fewer missed cases can mean more continued assessments. Paired outcomes at the same threshold show that exchange; separately reported performance figures can conceal it.

What to watch: Deployment decisions need evidence of how clinicians use recommendations and what happens to patients. An offline image score cannot supply those outcomes; early live evaluation examines the interaction between the tool, its users and care.

Read the full story
—
Back to the briefing
Original story: analysis

DriveMind's simulated gain masks an intersection setback

Bench2Drive scores route progress and clean finishes separately.

The big change

What changed: DriveMind passes weighted interpretations to control, raising overall scores against its same-pipeline single-interpretation baseline.

Why it matters: Bench2Drive separately measures scored route progress and clean completion. A better overall score need not reflect every scenario. Signalized intersections expose that gap in DriveMind's results.

What to watch: The repository still lists the tracker, controller, evaluation scripts and checkpoints as forthcoming. Their release would let researchers attempt the same-pipeline comparison and inspect route counts behind the intersection percentages. BIG CHANGE has not run DriveMind; road performance remains unestablished.

Read the full story
—
Back to the briefing
Original story: analysis

HachimiDock publishes source for its voice-task release

HachimiDock 0.1.167 source is public; voice-task behavior needs direct tests.

The big change

What changed: The maintainer reports focus-based voice targeting and fixes for task submission, reply matching and pet speech.

Why it matters: The usage guide separates writing a voice draft from sending it. Focus and input-control permission affect which conversation receives that draft, so a visible draft alone does not establish a completed task.

What to watch: Client 0.1.167 source can be inspected; its version label does not prove installed behavior.

Read the full story
—
Back to the briefing
Original story: analysis

Gartner survey finds 44% struggle to show AI returns

The 44% figure reports difficulty demonstrating AI returns, not measured profitability.

The big change

What changed: Gartner's survey makes difficulty proving AI returns visible while leaving project-level financial outcomes unknown.

Why it matters: A productivity gain can be useful without yet becoming an attributable financial gain. Investment decisions therefore need an outcome and a cost account for the same work and period; distinct survey measures cannot substitute for that project-level evidence.

What to watch: Stronger return claims would disclose the financial result, the full costs and the comparison used to estimate what would have happened without AI. They would also show the limits of that comparison. Until then, the payoff remains unresolved.

Read the full story
—
Back to the briefing
Original story: news

StationOne adds AI routing and budgets for marketing teams

StationOne adds routing and budgets; savings remain unverified.

The big change

What changed: Kochava says Enterprise teams can route by task complexity and set token or dollar budgets.

Why it matters: Visibility and control answer different management questions. One helps trace where spending occurred; the other determines what can happen when a budget is reached. A team can see a rising cost without having a rule that prevents the next charge.

What to watch: The release names no build or public Enterprise price. A purchaser needs to establish access and evaluate completed work under the same acceptance standard.

Read the full story
—
Back to the briefing