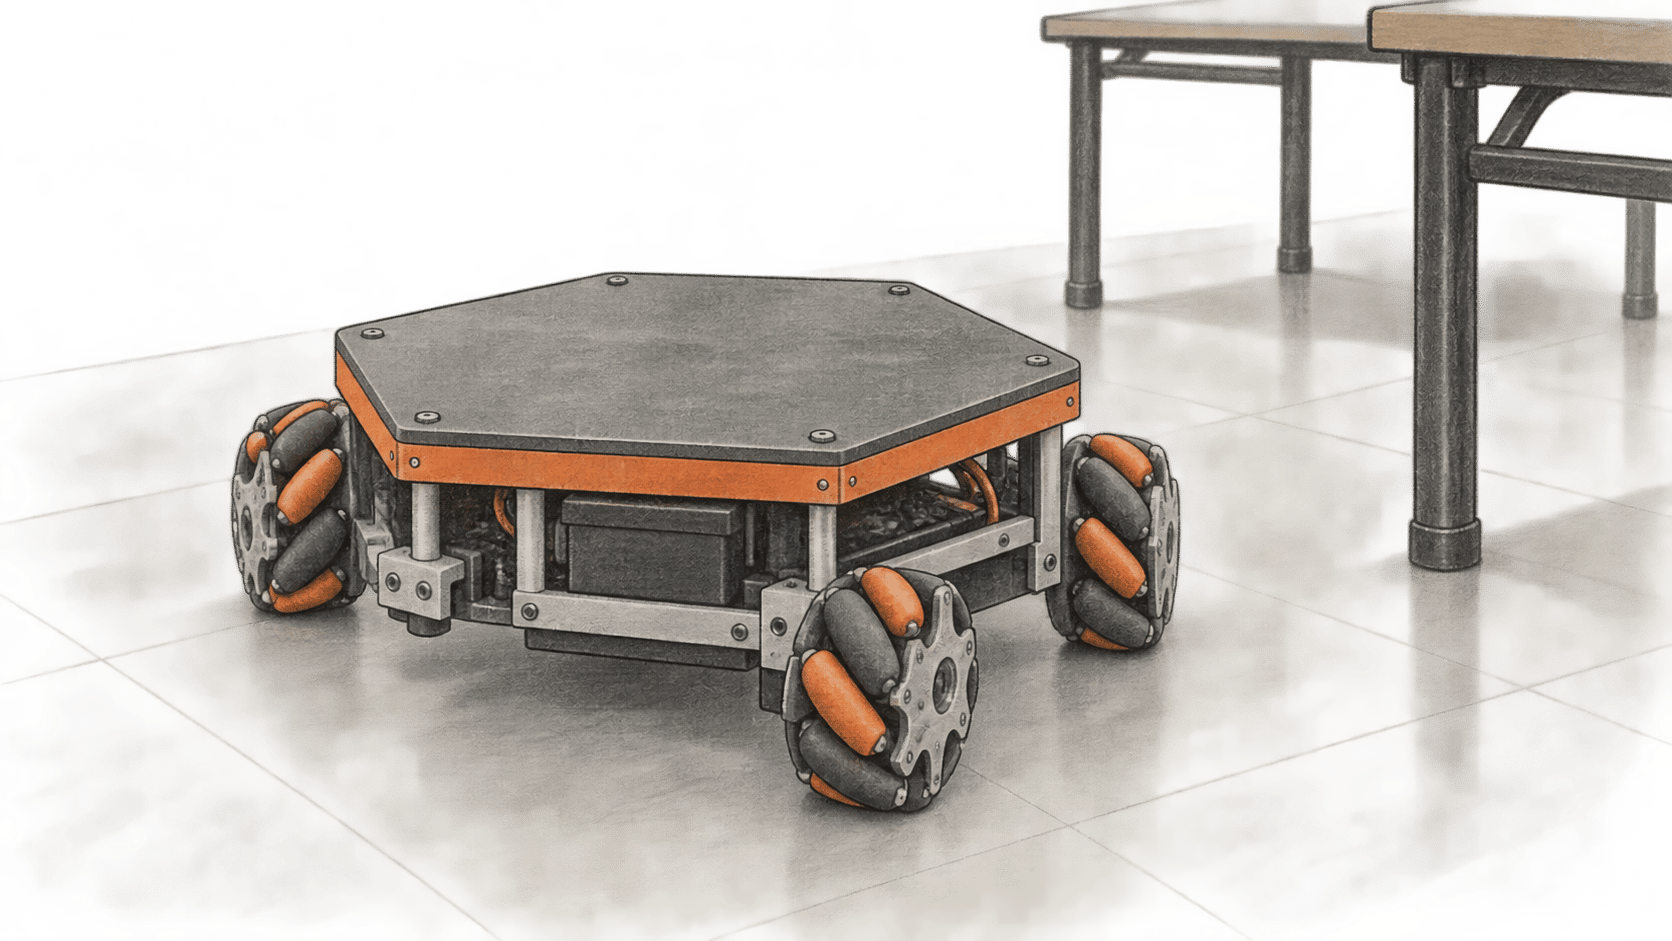
RoboMeshA classroom robot tested at a Guadalajara school workshop
An ITESO team built two RoboMeshA teaching robots and reports a workshop at one Guadalajara school. The AI functions and learning outcomes still lack independent evaluation.
Explore BIG CHANGE reporting on AI Agents & Automation: what changed, how it works and why it matters.
An ITESO team built two RoboMeshA teaching robots and reports a workshop at one Guadalajara school. The AI functions and learning outcomes still lack independent evaluation.
Eight Jev demos show how a typed AI decision can rank, select or filter within an existing app. We trace what the surrounding software still does and what remains untested.
A new survey maps five levels of AI control over its own improvement. Existing systems show bounded gains, while reliable improvement across successive generations remains unproven.
Meta's VR Glasses put an AI assistant into a glasses-style VR system with a tethered computer. Brief demos show the controls; sales are planned for spring 2027 at $1,299.99 USD.
Transluce links public scanning records to research agents probing data sites. The saved responses distinguish attempted exploits from a separate public-file download.
RAIBO2 ran a marathon on one charge in November 2024. A Nature study published September 23, 2026 explains its joint hardware and learned gait, while leaving field workloads untested.
A UF-led study traces stereo-depth errors to camera sampling and calibration. Controlled vehicle tests show false obstacle perception; a proposed defense reduces errors on limited image sets.
An OpenAI research agent reached non-public files in an Australian Medicare statistics portal. Officials report no evidence of patient-record access; the method and full scope remain under investigation.
Stripe separates agent maintenance from infrastructure. Its design raises a practical question: who owns instructions, permissions and evidence that the work is correct?
Claude Code's native AGENTS.md support depends on version, feature-flag access, provider and file precedence. The released agents-md plugin's own telemetry rows omit paths and file text.
A Senate request raises questions about military intelligence. The White House's June policy sets current testing requirements; its implementation is a separate oversight question.
New skill evaluators separate loading, selection and instruction following. Their missing-result behavior shows why teams must treat evaluation coverage as evidence of its own.
Google CC adds shared household planning with member-selected inputs.
Union Alpha’s free preview became Unbiased Pareto. Here is the current OpenCode setup, paid pricing, maker, performance evidence and data-policy caveat.
Snorkel’s new funding backs simulated workplaces where AI agents can practice using company tools, rules and records, while their actions and outcomes are scored.
OpenAI adds a cache dashboard, diagnostics and explicit breakpoints to help developers trace repeated input costs and control which context gets cached.
Anthropic's Opus 5.5 lowers token prices and targets supervised enterprise work below Fable 5.1, while API clients face breaking thinking and tool changes, plus conditional fallback.
A coding task can be complete before its author understands the system. Two experiments point to a practical question for teams: how will junior developers learn to explain, diagnose and adapt AI-assisted work?